Source
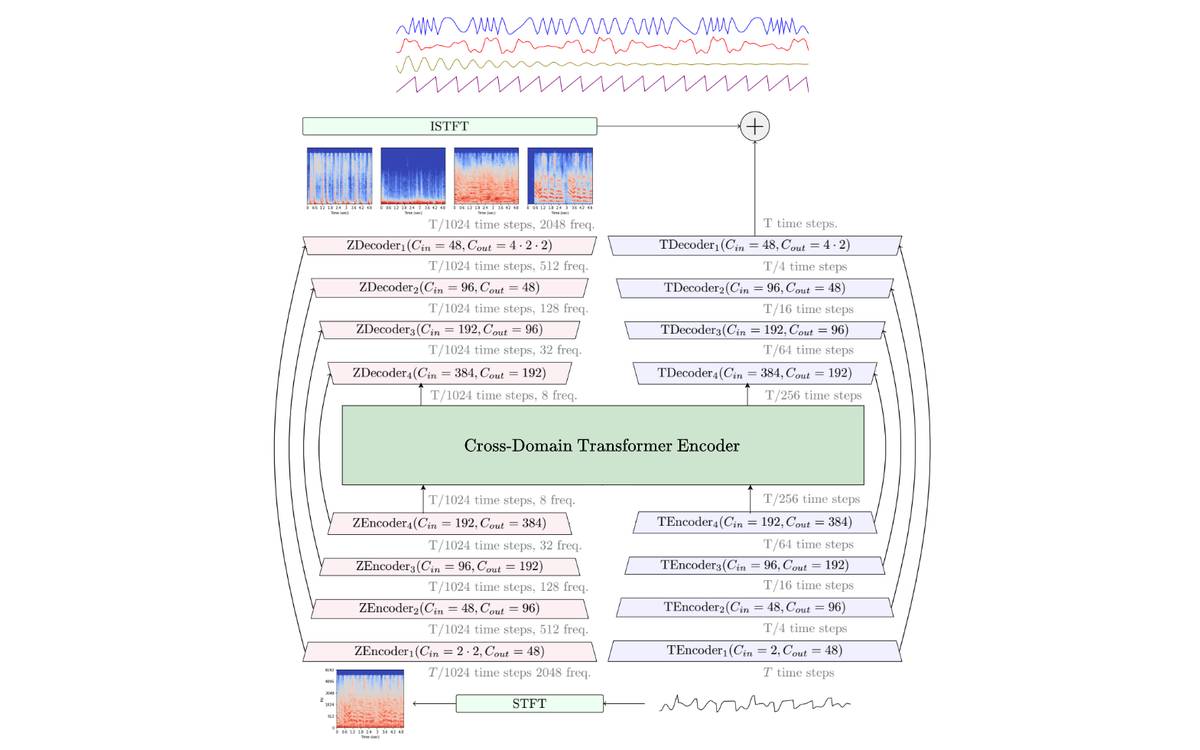
Demucs official documentation
Read the primary source.
Reference illustration, not a screenshot of this source.
Source-separation model · Voice
Separates audio sources such as vocals and accompaniment.
Use before transcription or mixing when music masks speech.
It does not transcribe or generate narration.
Mixed audio
Separated audio stems
Local model or an application such as voice-pro
Provider capabilities and historical Studio notes are distinguished below. Current account access, credits and runtime readiness were not tested.
Compute and model/weight terms; hosted wrappers charge separately.
Self-hosted if deployed locally, otherwise provider-dependent.
Exact model version determines support.
The right specialised layer for vocal separation; compare stem quality on the actual recording.
Decision: Use before transcription or mixing when music masks speech.
It does not transcribe or generate narration. Separation can introduce artefacts; it cannot recover every obscured word.
Official capability documentation; no listening benchmark
Catalogue review: 2026-09-05. The evidence note identifies what was verified. This date does not imply a fresh tool test or verification of every linked source.