Start with Kokoro or CosyVoice. Match its inputs and operating requirements to your job. Other equally rated options appear below.
Speech engine or client
Kokoro
★★★★☆ 4/5 for this task
Editorial task fit based on the documented role and integration requirements. Not the choice when reproducing a particular reference speaker is mandatory; check language and voice support.
Give it
Text; Reference audio where supported
Get back
Speech audio
How it runs
Engine/client, often exposed through voice-pro
Processing location
Local when self-hosted.
Charging model
Local inference compute; check distribution terms.
Choose it when
Choose for lightweight speech synthesis using available voices.
Watch for
Not the choice when reproducing a particular reference speaker is mandatory; check language and voice support.
Editorial task fit based on the documented role and integration requirements. This is an online client, not a local model. Do not infer a production service guarantee from a working client.
Give it
Text; Reference audio where supported
Get back
Speech audio
How it runs
Engine/client, often exposed through voice-pro
Processing location
Online service.
Charging model
Client uses an online service; check applicable terms.
Choose it when
Use for a simple online speech-generation route when that service dependency is acceptable.
Watch for
This is an online client, not a local model. Do not infer a production service guarantee from a working client.
Editorial task fit based on the documented role and integration requirements. Verify model weights, licence and reference preparation. Application code and pretrained weights may have different terms.
Give it
Text; Reference audio where supported
Get back
Speech audio
How it runs
Engine/client, often exposed through voice-pro
Processing location
Self-hosted if deployed locally, otherwise provider-dependent.
Charging model
Compute and model/weight terms; hosted wrappers charge separately.
Choose it when
Evaluate as a self-hosted reference-voice engine inside a supported application.
Watch for
The project distinguishes MIT code from non-commercial pretrained weights. Verify the intended use against the selected model terms.
Editorial task fit based on the documented role and integration requirements. Pin the version and test the intended language, reference voice and streaming mode.
Give it
Text; Reference audio where supported
Get back
Speech audio
How it runs
Engine/client, often exposed through voice-pro
Processing location
Self-hosted if deployed locally, otherwise provider-dependent.
Charging model
Compute and model/weight terms; hosted wrappers charge separately.
Choose it when
Choose when you need a controllable multilingual model route in an application you can operate.
Watch for
Pin the version and test the intended language, reference voice and streaming mode.
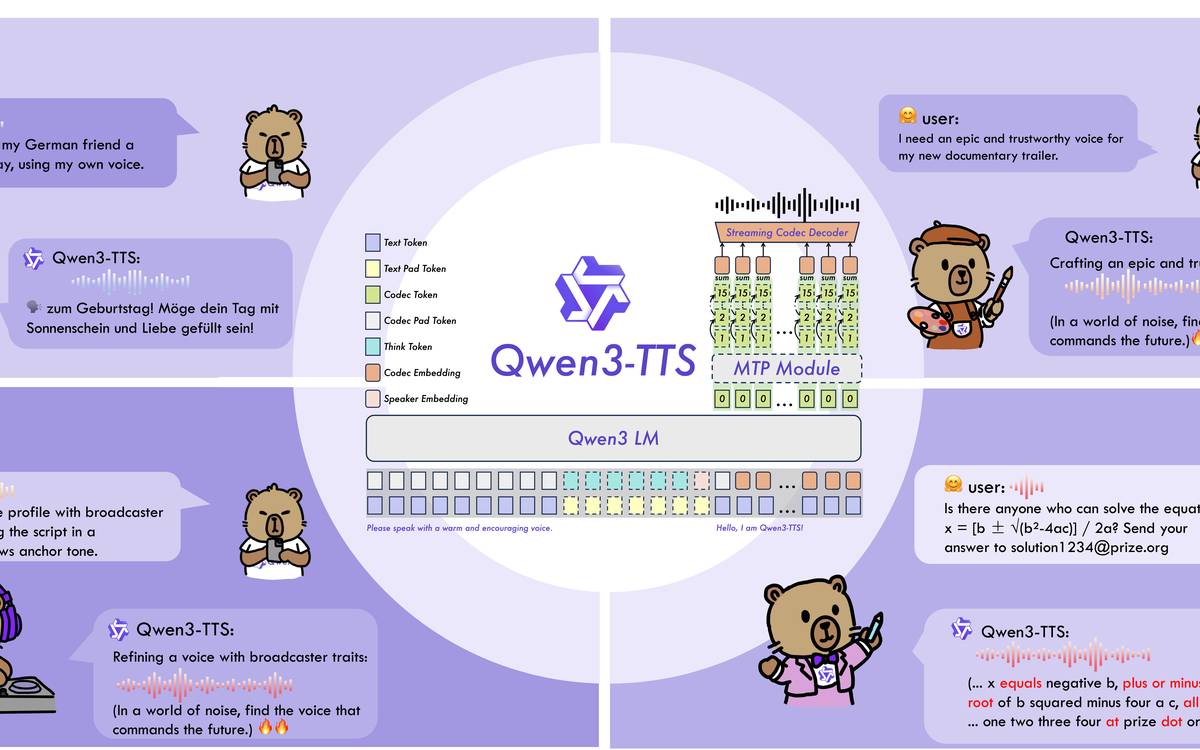
Editorial task fit based on the documented role and integration requirements. VoiceDesign, CustomVoice and Base are different models. Pick the correct one; advertised cloning input length is not an output-quality guarantee.
Give it
Text; Reference audio where supported
Get back
Speech audio
How it runs
Model runtime or compatible application
Processing location
Local/self-hosted, or selected cloud provider.
Charging model
Model compute; deployment or hosted-service charges.
Choose it when
Choose when you need instruction-led voice design or a supported cloning route.
Watch for
VoiceDesign, CustomVoice and Base are different models. Pick the correct one; advertised cloning input length is not an output-quality guarantee.
Editorial task fit based on the documented role and integration requirements. Versions and runtimes vary; compare pronunciation and delivery by ear before production.
Give it
Text; Reference audio where supported
Get back
Speech audio
How it runs
Model runtime or compatible application
Processing location
Self-hosted if deployed locally, otherwise provider-dependent.
Charging model
Compute and model/weight terms; hosted wrappers charge separately.
Choose it when
Choose for reference-voice speech generation when its supported version and language fit.
Watch for
Versions and runtimes vary; compare pronunciation and delivery by ear before production.
Editorial task fit based on the documented role and integration requirements. Check the released model and supported controls. A documented feature is not a verified local integration.
Give it
Text; Reference audio where supported
Get back
Speech audio
How it runs
Model runtime or compatible application
Processing location
Self-hosted/runtime dependent.
Charging model
Model compute; check the selected release and weights.
Choose it when
Evaluate when precise control over the generated speech is needed.
Watch for
Do not transfer capabilities between versions: the 2.0 release notes say precise duration control was not enabled; 2.5 documents a speaking-speed duration factor. Check supported languages.
Editorial task fit. Spanish now works in one Studio test, but its required encoder is non-commercial and it needs a large GPU or the Apple Silicon branch, so it stays below IndexTTS 2 / 2.5 (three stars) and Qwen3-TTS (four stars) as a general engine. Its instruction editing of existing speech goes further than any other engine in this task.
Give it
Written instruction with the text to speak; Reference audio to clone, or source audio to edit
Get back
Speech audio at 24 kHz; Edited, cleaned or separated recording
How it runs
Self-hosted Python runtime on a CUDA GPU, or the MLX branch on Apple Silicon; Gradio, ComfyUI and SGLang-Omni integrations
Processing location
Self-hosted if run locally; the public demo runs on Hugging Face.
Charging model
MIT weights, self-hosted GPU or Mac compute. Commercial use also needs a separate licence for the Qwen encoder.
Choose it when
Use the public demo to repair or extend an existing voice track (one word, one emotion, extra takes) and judge it by ear. Do not build a commercial product on it while the Qwen encoder licence stays research-only.
Watch for
The model card, instruction templates and published evaluations cover English and Chinese only. One Studio test on 27 September 2026 produced correct Spanish (see comparison notes); French is untested.; It needs the Qwen2.5-Omni-3B encoder, whose Qwen Research License allows non-commercial use only. The AuK weights themselves are MIT.; Output length is fixed in advance: pass a target duration, or let the optional prompt enhancer estimate it through a separate language model. No streaming. The demo caps a take at 30 seconds.; Launch-day peak GPU memory was about 25 GB; a 16 September update cut the encoder by about 7.5 GB and added CPU offload. Apple Silicon runs from a separate MLX branch; audio.cpp added offline GGUF runs on 20 September.; The free demo allows about one 30-second take a day without a Hugging Face token (measured 27 September 2026).
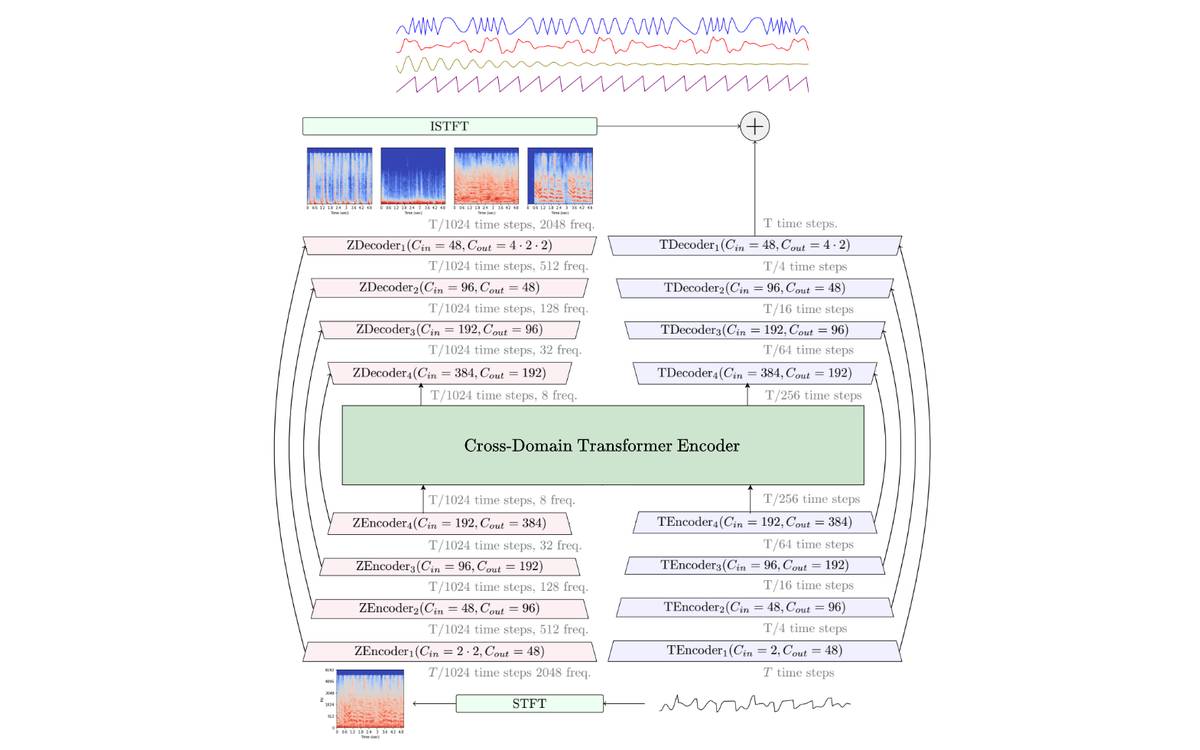
Start with Demucs. Match its inputs and operating requirements to your job.
Audio workflow application
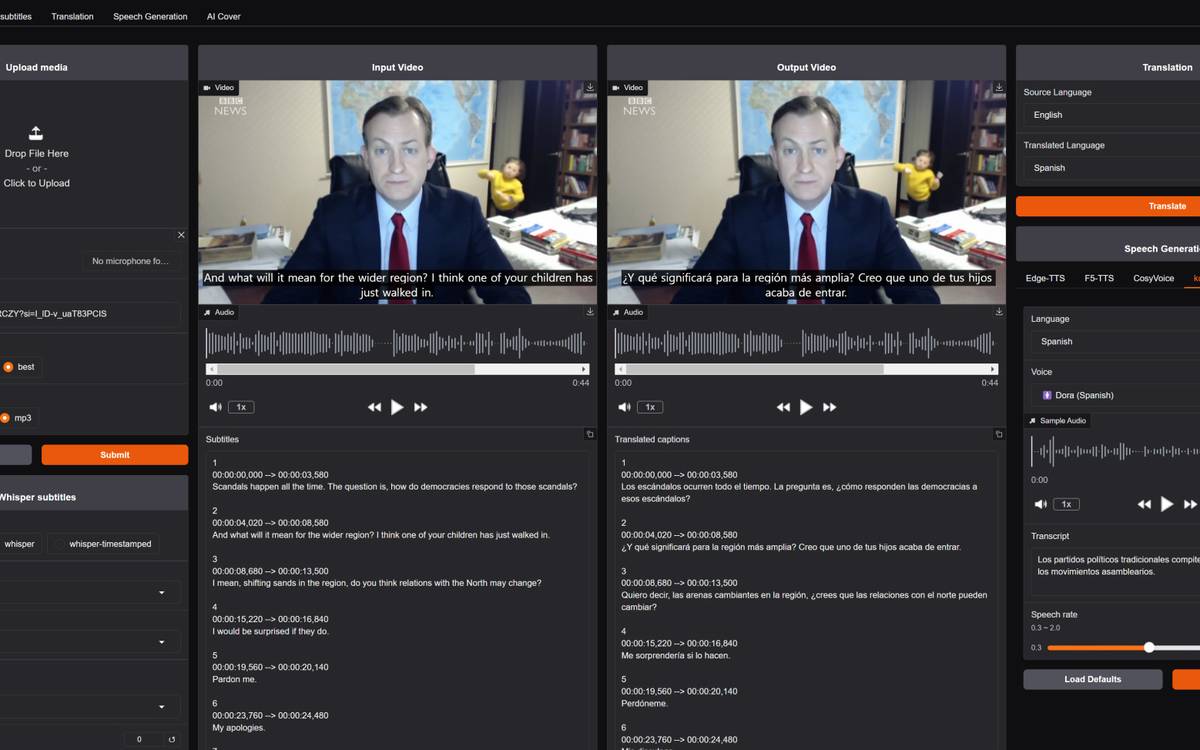
voice-pro
★★★★☆ 4/5 for this task
Choose the integrated interface when you want vocal separation plus surrounding audio tools. Demucs is an underlying separation engine, not a separate competing app.
Give it
Audio or video
Get back
Separated vocals; Subtitles; Speech
How it runs
Gradio interface around several tools
Processing location
Depends on the selected application, backend and hosting route.
Charging model
Check application, model and compute charges separately.
Choose it when
Use the interface for an assisted isolation workflow; use Demucs directly for a scripted separation step.
Watch for
Edge-TTS is an online client; installing the bundle does not make every feature local.
No evidence-based starting preference is assigned yet. Compare the documented inputs, outputs and operating requirements, then verify the option before using it.
Unresolved product label
Meta Voice Transcribe
Not rated
An ambiguous name cannot support a fair comparison.
Give it
Unverified
Get back
Unverified
How it runs
Unverified
Processing location
Depends on the selected application, backend and hosting route.
Charging model
Check application, model and compute charges separately.