Source
VibeVoice-ASR official documentation
Read the primary source.
Reference illustration, not a screenshot of this source.
Speech-recognition model · Voice
Model with documented structured transcription, speaker and timing output.
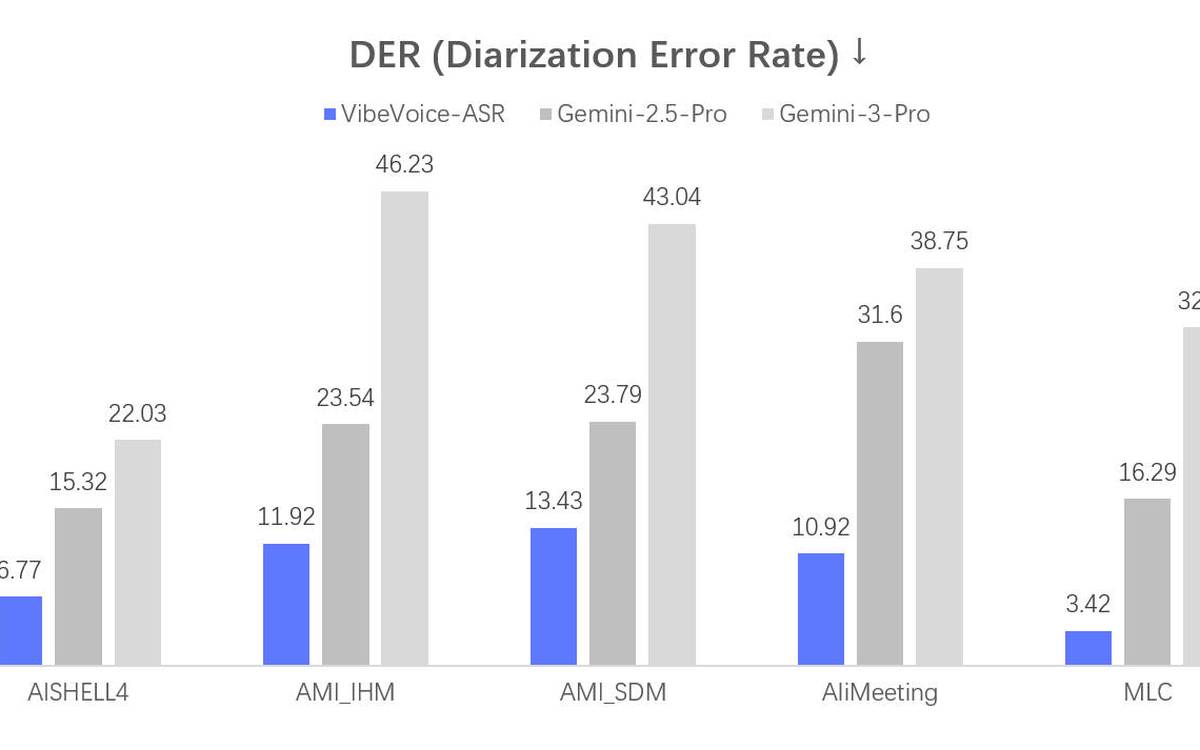
Evaluate when who-spoke-when output matters.
Not the same deployment as the CPU BitNet runtime already used locally.
Long audio recording
Structured transcript; Speaker labels; Timestamps
Model/runtime deployment
Provider capabilities and historical Studio notes are distinguished below. Current account access, credits and runtime readiness were not tested.
Compute and model/weight terms; hosted wrappers charge separately.
Self-hosted if deployed locally, otherwise provider-dependent.
Exact model version determines support.
Good capability fit on paper, but the required output needs verification in the chosen runtime before becoming the default.
Decision: Evaluate when who-spoke-when output matters.
Not the same deployment as the CPU BitNet runtime already used locally. Do not advertise structured output as proven locally. Streaming ASR is a separate release.
Official capability documentation; no listening benchmark
Catalogue review: 2026-09-05. The evidence note identifies what was verified. This date does not imply a fresh tool test or verification of every linked source.