Source
Moshi official documentation
Read the primary source.
Reference illustration, not a screenshot of this source.
Dialogue model and framework · Voice
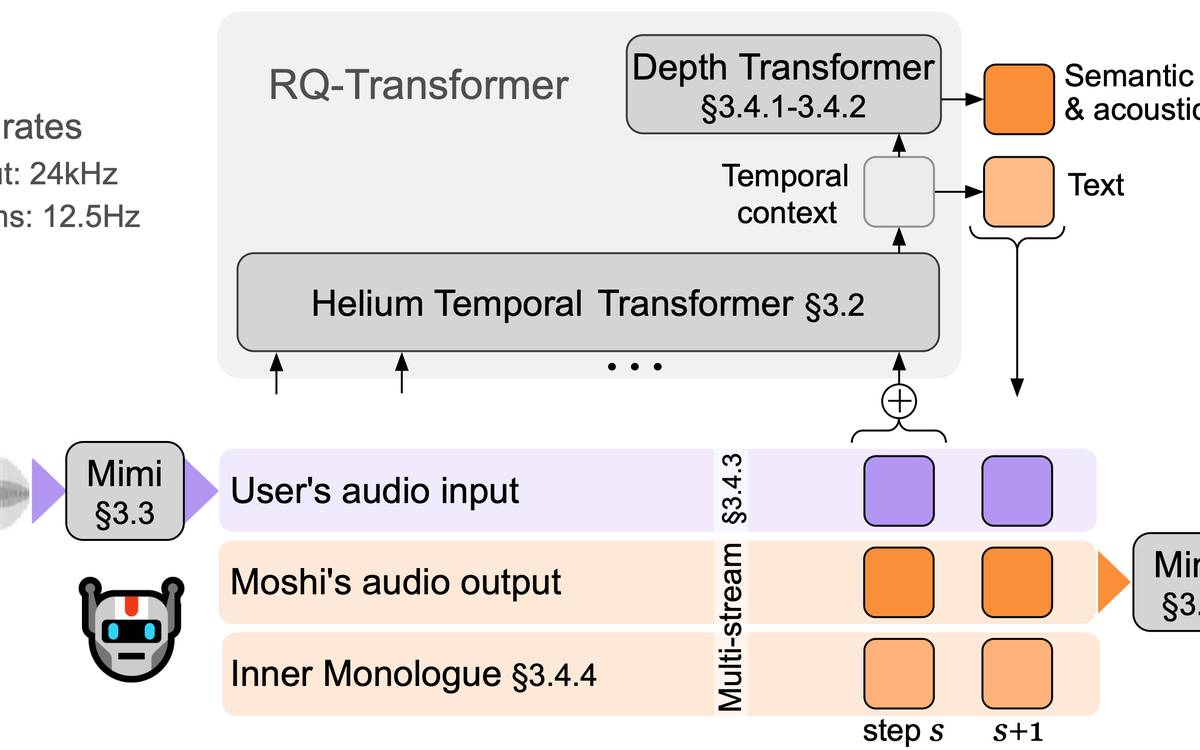
Speech-text model and full-duplex spoken-dialogue research framework.
Evaluate when research-level control over full-duplex dialogue is the objective.
Not the simplest production route for a website guide.
Live audio
Spoken dialogue
Self-hosted model/runtime
Provider capabilities and historical Studio notes are distinguished below. Current account access, credits and runtime readiness were not tested.
Compute and model/weight terms; hosted wrappers charge separately.
Self-hosted if deployed locally, otherwise provider-dependent.
Exact model version determines support.
Distinct from a modular ASR-LLM-TTS stack; useful to evaluate, with substantial deployment work.
Decision: Evaluate when research-level control over full-duplex dialogue is the objective.
Not the simplest production route for a website guide. Validate languages, hardware and behaviour on the intended conversation.
Official capability documentation; no listening benchmark
Catalogue review: 2026-09-05. The evidence note identifies what was verified. This date does not imply a fresh tool test or verification of every linked source.