Source
Whisper official documentation
Read the primary source.
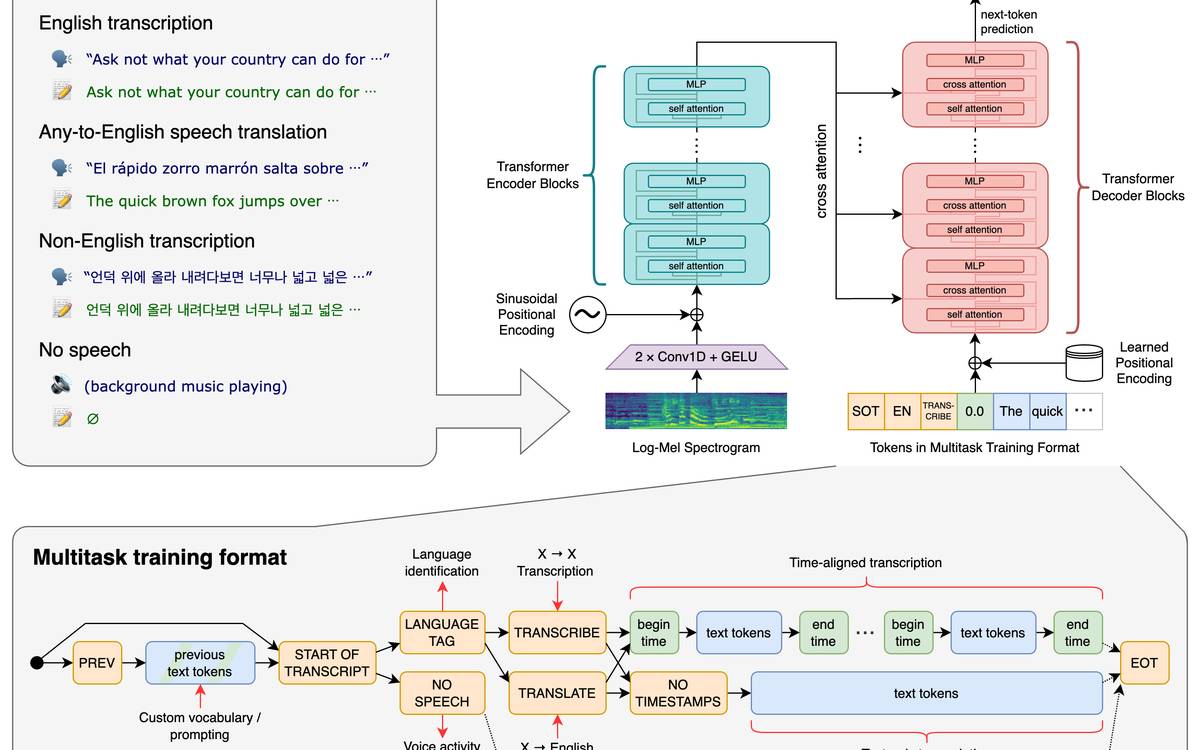
Reference illustration, not a screenshot of this source.
Speech-recognition model · Voice
Open speech-recognition model for transcription, translation and language identification.
Use as a general multilingual transcription engine or baseline.
Speaker identification requires a separate diarisation layer.
Audio file
Transcript; Timed segments
Local runtime or a hosted service running Whisper
Provider capabilities and historical Studio notes are distinguished below. Current account access, credits and runtime readiness were not tested.
Local compute, or hosted-service charges.
Local when run locally; cloud when used through a hosted endpoint.
Multilingual; accuracy varies by language and model.
A clear, reusable transcription baseline. Language and hardware affect results; no universal accuracy ranking is implied.
Decision: Use as a general multilingual transcription engine or baseline.
Speaker identification requires a separate diarisation layer. Check names and technical terms; distinguish the open model from hosted transcription products.
Official capability documentation; no listening benchmark
Catalogue review: 2026-09-05. The evidence note identifies what was verified. This date does not imply a fresh tool test or verification of every linked source.