Source
InfiniteTalk repository
Read the primary source.
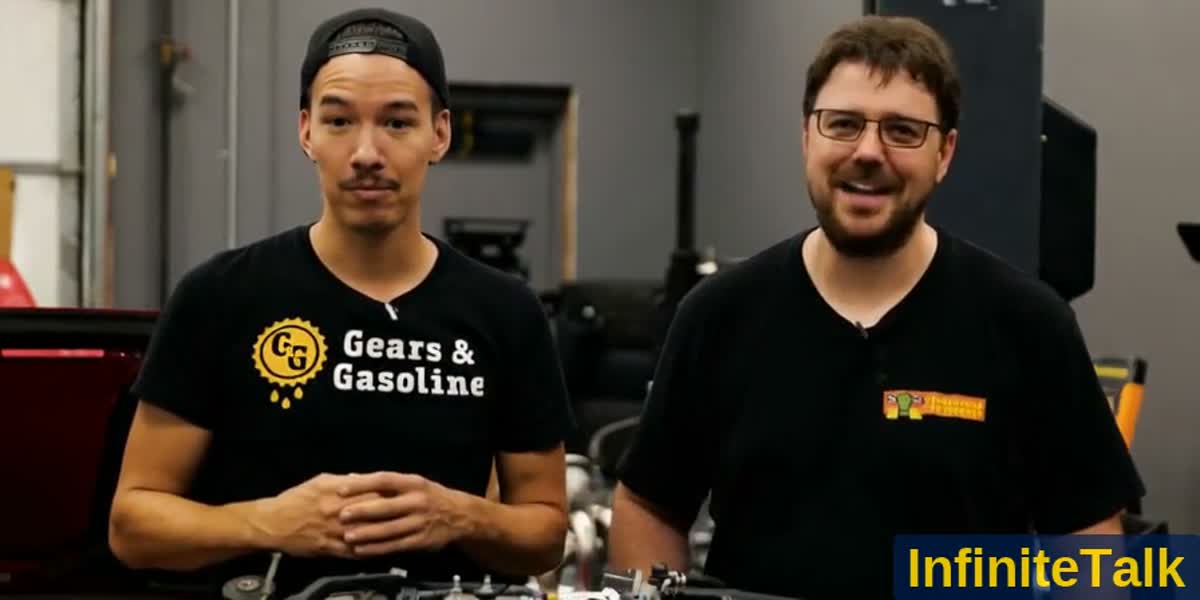
Reference illustration, not a screenshot of this source.
Open audio-driven avatar model · Video · Speakers
Turns a portrait or a clip and an approved audio track into a speaking video with head and body motion. Open weights from MeiGen-AI.
The cheapest measured route for a portrait speaking our own audio: identity held, about $2.30 a published minute at 480p on WaveSpeed.
Not for sealed lips on b, p and m in French from a small portrait: four variants failed Frank's eye on 14-09-2026.
Portrait image or clip; Approved audio; Optional prompt
Speaking video, 480p or 720p
Hosted API (WaveSpeed $0.03 a second at 480p) or open weights in WanGP on a rented card; measured 14-09-2026
Provider capabilities and historical Studio notes are distinguished below. Current account access, credits and runtime readiness were not tested.
WaveSpeed $0.03 a second at 480p, $0.06 at 720p (read 14-09-2026); measured $0.12 for 3.1 s.
Provider-hosted on WaveSpeed; self-hosted on a rented card.
French tested by us: identity and rhythm pass, bilabial closures fail at 480p.
The only born-whole route measured on our own speaker: identity held, about 70 s and $0.09 to $0.12 for a 3 to 4 s clip at 480p. Lip shapes on bilabials failed Frank's eye.
Decision: Start here for a moving speaker on approved audio; check the b, p and m frames before approving.
Same family as LongCat-Video-Avatar: the whole person is generated from portrait and audio, not a mouth repainted on an existing clip.
Measured on our own speaker 14-09-2026: six hosted clips, cost and wall clock read, judged by Frank
Catalogue review: 2026-09-15. The evidence note identifies what was verified. This date does not imply a fresh tool test or verification of every linked source.
Source
Read the primary source.
Reference illustration, not a screenshot of this source.
Source
Read the primary source.
Reference illustration, not a screenshot of this source.