Source
LatentSync official source
Read the primary source.
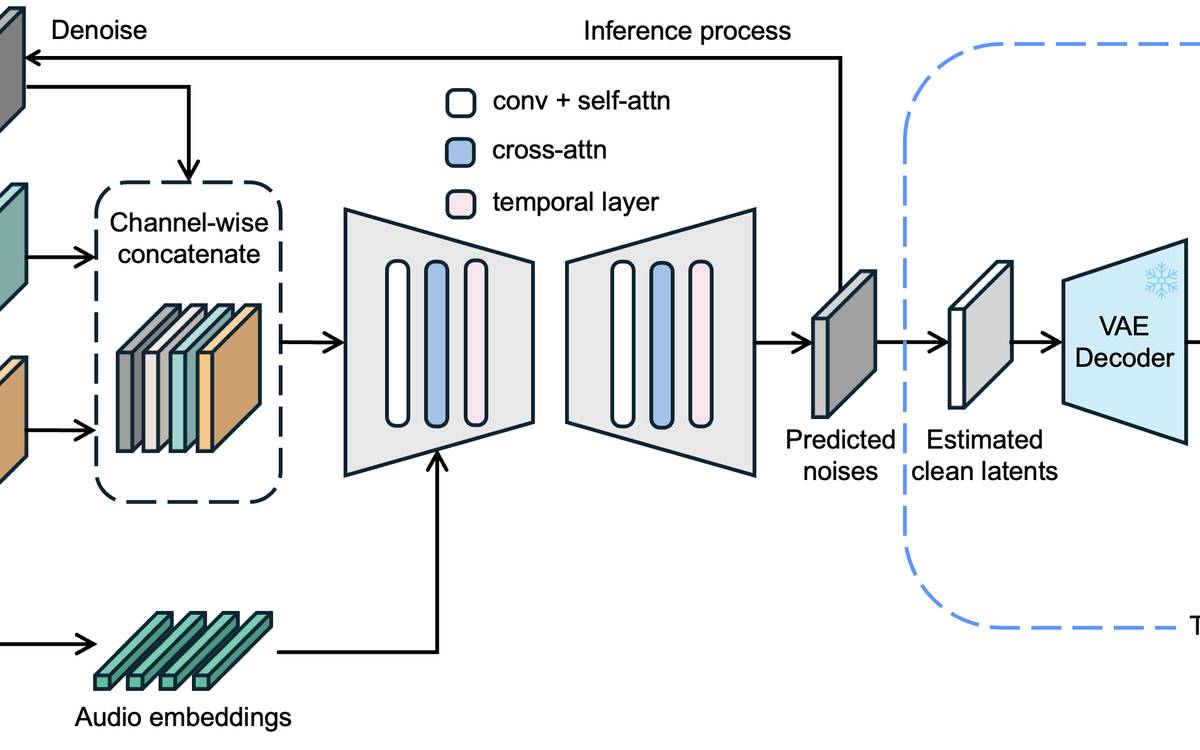
Reference illustration, not a screenshot of this source.
Lip-sync diffusion model · Video · Speakers
Audio-conditioned lip synchronisation for existing video.
Compare against MuseTalk using the same face clip and approved audio.
Not a complete talking-person workflow by itself.
Face video; Approved audio
Lip-synchronised video
Application/API or supported runtime; access not rechecked
Provider capabilities and historical Studio notes are distinguished below. Current account access, credits and runtime readiness were not tested.
Compute and model/weight terms; hosted wrappers charge separately.
Self-hosted if deployed locally, otherwise provider-dependent.
Exact model version determines support.
A true same-stage alternative to MuseTalk; final choice needs visual inspection, not unrelated model scores.
Decision: Compare against MuseTalk using the same face clip and approved audio.
Not a complete talking-person workflow by itself. Version changes affect memory and output; more guidance can distort the face.
Official capability documentation; no comparative production benchmark
Catalogue review: 2026-09-05. The evidence note identifies what was verified. This date does not imply a fresh tool test or verification of every linked source.