 Studio › Voice · 31-07-2026 · method: voice-agent skill
Give a page a voice
Three different jobs: recorded narration, a conversational guide, and speech paired with a moving face. Each needs its own tool and verification.
A page that reads itself
Recorded segments. The reader presses play, the voice explains, the page scrolls and opens the right part by itself.
 Check the guide status
A guide that answers
A configured conversation system can answer typed or spoken questions. Test grounding, microphone input and interruption on the actual deployed guide.
Check the guide statusA voice that moves a face
The same recorded voice drives a photo, so a person appears on the page and speaks. This crosses into  Speakers.
Check the guide statusTo give this page a voice: give your Claude the recipe, then ask
First, once per machine. Your Claude does not know this recipe until you give it to it. The recipe is a small file called voice-agent. Install it with one command in your Claude Code:
npx skills add gfrankgva/studio-skills
Or take the file yourself: download voice-agent and put it in ~/.claude/skills/voice-agent/. More ways, and what else is in the pack: further down this page.
Then just ask, in your own words: « A voice guide for this site. »
Choose the job before the tool
For everyday dictation, start with the existing FreeFlow workflow; use FluidVoice when a local-first configuration is the priority. For hosted narration, use the established ElevenLabs route; for local voice creation, compare Voicebox and VoiceStudio. For conversation, choose a platform or API and verify the complete deployed experience.
 Compare voice tools by task
Cloning requirements vary by model and route. Approve the voice by ear and check names before creating video. A narration file is not proof of a working dialogue system.
Historical voice workshop notes, July–August 2026
Preserved for provenance. Old prices, rankings, engine requirements and availability statements below are not current recommendations. Use the task comparisons for the reviewed selection guidance.
Make a voice
Cloning. Thirty seconds of clean speech is enough. Hosted clones live at ElevenLabs and keep their quality across languages; the free local alternative is Voicebox on the Mac, which costs nothing and never leaves the machine.
First rule: take a voice, do not clone one
Frank, 10-08-2026, « on peut trouver un autre modèle de dame française chez ElevenLabs, on devrait toujours faire ça. » The shared library carries thirty professional French female voices alone, and as many in Spanish, English or Arabic. Each is unlimited in length, identical from one sentence to the next, and costs about two centimes a line. Cloning is only for a real person who must be recognisable.
Why this is a rule and not a preference. Cloning an invented person cost a full night on Vox Populi: Hélène's voice existed only inside eight seconds of generated video, so every clone came back a near-twin and the ear refused it twice. The bank method below rescued it to within one per cent of the original, and it was still refused as « moins claire ». A library voice would have been settled in ten minutes.
How to choose, in ten minutes. Ask the API for the voices of that language and gender, generate the same sentence in five of them, and put the five files in front of the client. Never describe a voice in words; play it.
La excepción, medida el 24-08-2026: cuando el motor de la cara también hace la voz
La regla de arriba dice que a una persona inventada se le da una voz de biblioteca en vez de clonarla, y sigue siendo cierta cuando el vídeo y la voz se fabrican por separado. Deja de serlo cuando un solo motor genera la cara y la voz juntas, que es lo que hace Grok Imagine desde el 21-08.
La prueba, con Valentina y con el método de esta misma página, la misma frase y la misma imagen para que sólo juzgue el oído: un clon hecho con 90 s de su voz nativa, y después cinco voces profesionales de la biblioteca, entre ellas la colombiana y la que ya habla en su página de zonas francas. Frank eligió la voz nativa del motor las tres veces. Su palabra sobre la mejor de la biblioteca: «la 5 no está mal, pero prefiero la de Grok, más agradable».
Lo que cuesta esa preferencia, dicho claro, porque es una decisión de dinero: la voz de biblioteca sale a unos dos céntimos la línea y permite poner la boca con un motor abierto en nuestra propia GPU; la nativa del motor cuesta 0,65 dólares la línea. Treinta veces más. Se paga porque el oído lo pide, no porque no haya alternativa.
El método sigue valiendo y es lo que hay que repetir: veinte minutos y unos céntimos bastaron para cerrar las dos familias baratas antes de alquilar ninguna máquina. Nunca se describe una voz con palabras, se pone a sonar.
When the person has no voice yet, the voice bank
The method for every invented speaker, settled on Hélène, 10-08-2026. Frank: « c'est la meilleure méthode pour tous les avatars ».
The trap. An invented person is born from one master clip, eight seconds. Cloning from eight seconds does not imitate, it guesses: the clone comes back a near-twin at best, and the ear refuses it. Every service hits the same wall, because the wall is the material, not the tool. ElevenLabs wants thirty seconds for a decent clone and half an hour for its professional grade; HeyGen wants thirty to sixty seconds. Eight is below all of them.
The way out: manufacture the material. The engine that invented her can invent more of her. Generate several master clips of her speaking different sentences, sounds chosen for variety, not for broadcast, and you turn eight seconds into forty. Then clone on the forty.
The catch, and the answer to it. A generative engine re-invents the voice at every take: our second clip came out twelve hertz higher than the master. So the takes are measured, not trusted, pitch and timbre band by band against the master, and only the closest are kept as training material. Measure, select, then train.
What it costs, once. Six clips at about 0.65 USD each, roughly four euros, and the speaker has a voice bank for life: every later sentence costs about two centimes, in her voice, with no eight-second ceiling. Compare with re-generating each sentence on the video engine: 0.65 USD a line, a voice that drifts between lines, and a hard eight-second limit.
The recipe. make-voice-bank.py, generate makes the clips, measure ranks them against the master, train builds the clone on the best plus the master itself. Kept with Hélène at VoxPopuli/member-app/companion/face-a/, to be folded into the 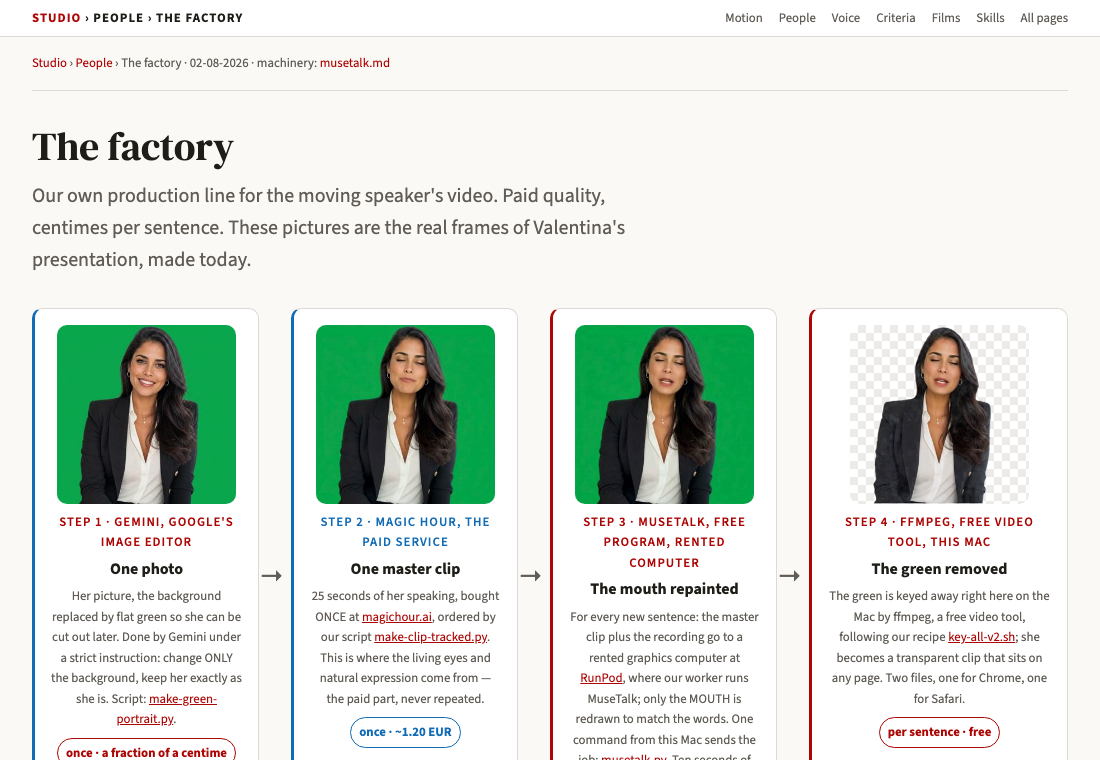 speaker factory.
Saying names right. Every voice needs a small pronunciation list. Acronyms are the trap: left to itself a voice guesses, and its guess drifts between takes. Write it in the list the way it must sound, AZFA is said as a word, "ásfa". This is a rule, not a detail. And the choice belongs to the ear that owns the name: we spelled the four letters out for three days until Frank heard the two side by side and chose the word.
The sound. A fixed treatment gives every recording the same body and presence, so segments recorded weeks apart still sound like one person.
Four traps, already paid for
- Typing is the door, not the microphone. A page opened as a file cannot capture a microphone at all. Typed question, spoken answer works everywhere; the microphone needs the page to be served.
- A clone is lost on the wrong model. Clones are trained per voice model. On the wrong one the person sounds like a stranger. Check before delivering.
- A public guide needs no key in the page. It connects without secrets, so the page can be handed to anyone, but anyone can also use its minutes: reserve it for documents given to a few people, or lock it to one site.
- Never let it speak first. A voice that starts by itself when a page opens ambushes the reader. The reader presses play.
The other direction, speaking to the machine
Everything above is the page speaking to a person. This is a person speaking to the machine.
Dictation, free. FreeFlow is an open Mac app that types what you say, anywhere: hold Fn and talk, let go and the words appear in whatever field the cursor is in. Frank moved to it from Wispr Flow on 12-08-2026 after a year of Wispr mishearing him. It costs nothing beyond a Groq key, and it is better than the paid one for one reason: you can teach it your words. A vocabulary list carries eRegistrations, OHADA, Lesotho, Bitácora and the rest, so the cleanup step stops inventing spellings.
Commands by voice. The cleanup step is a prompt, so it can be taught anything. Ours knows Frank's slash commands: say "slash pick up the ABC system" and it writes /pickup the ABC system, lowercase, one word, no full stop. Say a sentence with "pick up" in it and nothing happens. That rule lives in the app's own prompt.
Two traps, both paid for on day one. Two dictation apps fight over the same key, the second one starts listening and never stops, which looks exactly like a freeze. And left the language on automatic, the model hears a short English sentence, decides it was French, and hands back a French translation. Fix the language, and keep one app.
Tap twice to keep talking. Holding a key through a long passage is uncomfortable. We added a double tap to the app ourselves and gave it back to its maker: pull request 291. Tap Fn twice, speak as long as you like, tap once to stop.
The whole recipe, the settings and the traps: the kit.
A voice that answers back
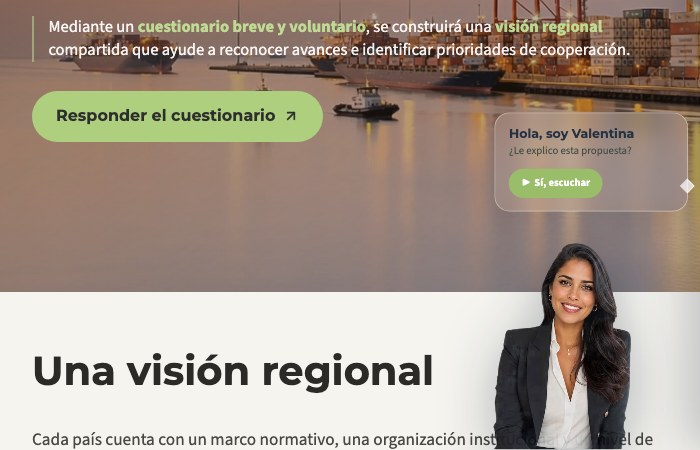
Shape 2 above, rebuilt so it can run on our own machine. This is the next stage: Valentina explains today, and she should answer.
The stack. Hugging Face's  speech-to-speech is a full conversation pipeline, it hears the silence that means you stopped, transcribes, thinks, and speaks back, with every one of those four parts swappable. Apache 2.0, and it already runs as the conversation brain of the Reachy Mini robots. Installed at
3 - Projects/voice-to-voice/.
Why it matters more than another engine. It speaks OpenAI's Realtime protocol. Anything built against OpenAI can be pointed at our own server by changing one address, so a page can start hosted and move sovereign later without being rebuilt. That is the answer to the sentence that ends every ministry conversation: the citizen's voice never leaves the country.
What it does not replace yet. ElevenLabs still wins on the voice itself, and its interruption handling is why we chose it. Keep ElevenLabs for anything a minister hears this year; build the open one behind it and compare with the ear, not with the specification.
Listening at length. Microsoft's  VibeVoice covers the third case: an hour of recording in one pass, in over fifty languages, switching language by itself inside one file. Measured on Frank's own Mac 30-08-2026, not taken from the headline: it returns plain text only, with no speaker labels and no timings, and a name it cannot hear stays wrong even when handed to it in advance. For who spoke and when, use FluidVoice, which does label speakers. What Frank owns and what each one really gives: the kit. Corrected 30-08-2026, checked on the repository itself: this page used to say its speaking half had been withdrawn. It has not. The project is alive, MIT, and still shipping on both sides: a realtime speaking model with voices in nine languages, and the listening half above. The part to take is VibeASR.cpp: the same hour-long, who and when and what transcription squeezed from 4.6 GB to 1.6 GB and running faster than real time on a plain processor, no graphics card. That is the meeting recording read on his own Mac, for nothing.
The tools, and which is best
How to read the stars. They rank a tool for this job, from what we have run ourselves, not from its reputation. ★★★★★ our default, proven in something delivered · ★★★★ good, second choice or one particular job · ★★★ works, with a real limit · ★★ tried, not adopted · ★ do not use, and the reason is written.
| Tool | What it does for a voice | How we drive it | Cost | Verdict |
|---|---|---|---|---|
| ElevenLabs | Clones a voice from thirty seconds, holds its quality across languages, and answers live in convai | API key, and the voice-agent skill for a live one | Paid, per character | ★★★★★ Default when the voice must convince, and the only one of these that holds a conversation |
| Voicebox | Cloning and reading aloud, entirely on the Mac, nothing leaves the machine | Local app, API on port 17493 | Free | ★★★★ The sovereign path when a country will not send its voice abroad. It does not hold a dialogue |
| Groq · Whisper large v3 turbo | Turns speech into text, including a twelve-minute video | Groq key, one curl | A fraction of a centime | ★★★★★ Nothing else comes close on price for the same accuracy |
| FreeFlow | Dictation into any field on the Mac, with a word list it can be taught | Hold Fn, or tap twice; runs on the same Groq key | Free | ★★★★★ Frank's daily tool since 12-08-2026, and the only one that learns his vocabulary |
| Wispr Flow | The paid dictation app he used for a year | — | Paid | ★ His verdict, 12-08-2026: « very, very bad ». Keep it closed, two dictation apps fight over the same key |
| OpenAI realtime | Two-way voice, hosted, over their own protocol | API key | Paid, per minute | ★★★ Credible, but nothing of ours has shipped on it yet. Rated on the mechanism, not on our experience |
| NVIDIA Nemotron VoiceChat | Full duplex on our own server: it listens while it speaks | Early access, approved 27-07-2026 | Free, our own machine | ★★★ English only today. A bet on sovereignty, not a production choice |
Cleaning and subtitling a recording
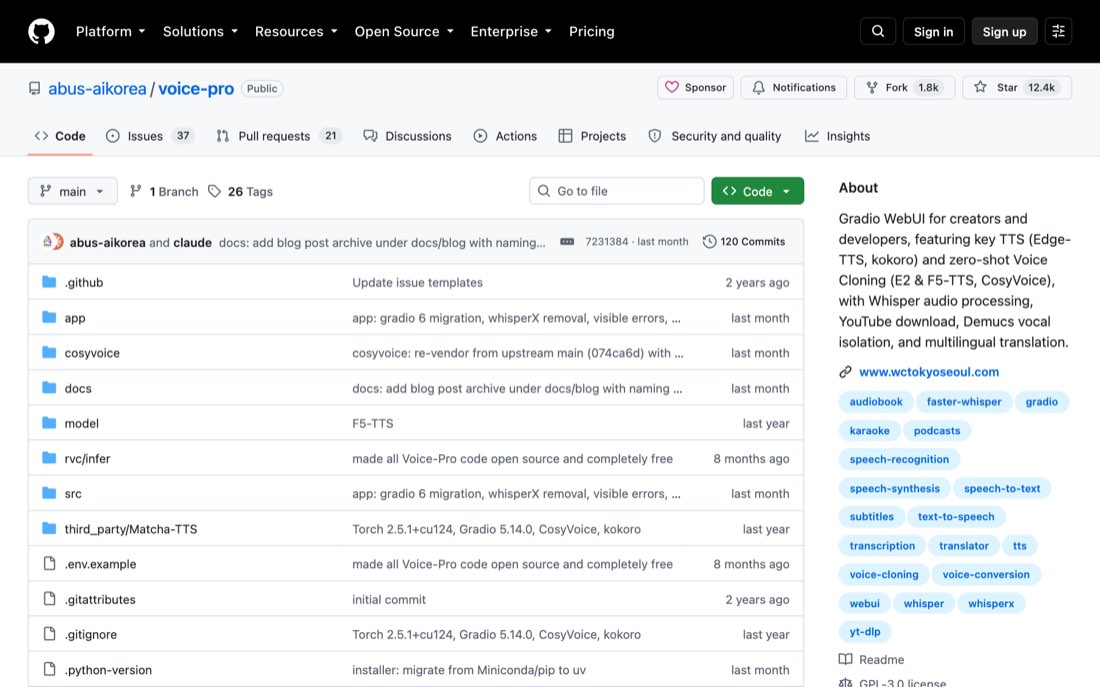
What we did not have until now. Everything above makes a voice or reads one. Two jobs were missing: pulling a voice out of a noisy recording, and turning a recording into subtitles in another language. One free bundle does both.
| What it adds | What it does | Where it runs | Verdict |
|---|---|---|---|
| Voice out of noise | Demucs separates a voice from music and background. A take with a fan, a street or a soundtrack under it becomes a clean voice track | The rented computer, or the Mac | ★★★★★ Nothing of ours could do this. It also makes a usable sample for cloning out of a recording that was unusable |
| Subtitles, translated | Whisper writes the words with their timings, and the file can be translated, so a clip gets subtitles in another language | Same | ★★★★ We do this by hand today |
| Free cloning and reading aloud | Kokoro and Edge for reading, F5-TTS and CosyVoice for copying a voice from a few seconds | Same | ★★★ Useful when nothing may leave the machine. For a voice that must convince, ElevenLabs is still ahead |
The whole thing is one web page you open (voice-pro, GPL-3.0), installed next to WanGP on the rented computer: WanGP is the bundle for pictures and video, this one is the bundle for sound.
What it costs
| Way | What it is | Cost |
|---|---|---|
| ElevenLabs, hosted | Cloned voice, recorded narration and the live guide. What Valentina and Zalia use today. | Subscription plus minutes |
| Voicebox, on the Mac | Cloning and narration, offline, nothing sent anywhere. | Free |
| FreeFlow, on the Mac | Dictation into any field, with our own vocabulary and our own slash commands. Replaced the paid Wispr Flow on 12-08-2026. | Free, on the Groq key |
| speech-to-speech, ours | The two-way guide, hosted by us, speaking OpenAI's Realtime protocol so any client can point at it. Apache 2.0. | Only the machine it runs on |
| Our own machine | The whole live guide hosted by us on a rented graphics computer (RunPod, ~0.34 USD/h, billed by the second). NVIDIA's Nemotron early access belongs here: it answers in under a third of a second and can be interrupted like a person, English only today, so a bet, not a tool. | About 0.34 USD an hour of machine |
Give it to a colleague
This whole page is a skill, a small file of instructions their own assistant reads and follows: a grounded voice that answers visitors from facts you wrote. They install it once; after that they simply say what they want, in their own words, and their assistant does it, on their own machine, with their own accounts, nothing of Frank's.
One command, in their Claude Code:
npx skills add gfrankgva/studio-skills
That installs this skill together with the studio's six others.
Or take the file itself: download the skill (one file, put it in their ~/.claude/skills/voice-agent/) · read it on GitHub · the whole pack.
Without the skill it still works, the method on this page still works by hand. The skill only means their assistant already knows it.
Where conversation stands today, speaker by speaker (Zalia live and tested · Valentina wired, closed · Grace parked), with the ranked improvement tracks:  the interaction diagnosis. The speaker herself, sizes, buttons, factory: Speakers.